Hire Databricks Developers to Cut Pipeline Time and Cloud Costs
Our Databricks engineers reduce data processing from eight hours to forty minutes. Analysts answer questions the same day instead of the week. Cloud bills drop. Queries stop scanning entire datasets and pull only recent records. DATAFOREST has spent 18 years building data systems — our in-house team knows what breaks.


PARTNER

PARTNER

FEATURED IN
01
Dedicated Databricks engineer (Full-Time)
- The engineer focuses on pipelines —> Delta tables —> data lineage —> compliance.
- They rewrite jobs, process CDC data, and monitor daily operations.
- You pay a monthly subscription and scale the team as needed.
02
Team extension / Squad model (2–5 Engineers + TL/PM)
- Executes comprehensive migration from SQL to the Databricks analytics platform.
- Rewrites legacy scripts into automated tasks.
- Builds large-scale Databricks lakehouse architecture.
- Creates a multi-layered approach for a single source of truth.
- Implements dashboards, CDC data ingestion, and Databricks cost reduction.
- Fits complex, undocumented environments with multiple data sources.
03
Fixed-scope Databricks project delivery
- This agreement defines an exact timeline and a strict budget.
- The data team deploys the complete Medallion architecture.
- Engineers build production pipelines, system monitors & business dashboards.
- This model fits clear data migrations and planned transformation stages.
04
POC (2–4 Weeks)
- Checks Databricks feasibility before migration.
- Creates the first bronze to silver to gold data flow.
- Demonstrates computing resource savings and lineage transparency.
- Provides a low-risk starting point for enterprise migration.

We implemented 37+ AI/ML projects for our enterprise clients. This large volume of work taught us a clear lesson. We know the exact places for valuable predictive models. Basic logic works much better in other specific product areas.

We employ over 100 software engineers. A large workbench means you avoid waiting three months to staff a project. One person can take over for another without starting from scratch.

We bring 18 years of data engineering experience. Across projects, our Databricks specialists have seen recurring failure modes and know which shortcuts create technical debt and remove unnecessary work.

We maintain a 92 percent customer retention rate. That gives clients a clearer signal about continuity, communication, and long-term delivery.
01
100+ software engineers
A large workbench means you don’t have to wait three months to staff a project when you hire Databricks developers from us. When one person leaves or gets sick, someone else takes over without having to start from scratch.
02
18+ years of data engineering experience
Problems recur across industries. This long experience means the team you hire Databricks developers has seen most failure modes and knows which cuts create technical debt and which save weeks.
03
92% customer retention rate
Service providers lose half of their customers every year. This number speaks to fewer surprises, realistic deadlines, and code that doesn’t break two weeks after handover when clients hire Databricks developers here.
04
37+ AI solutions implemented
AI projects fail more often than they succeed. Implementing so many solutions means understanding where models add value and where simpler logic works better, and how to deploy them without constant babysitting once you hire Databricks developers with this track record.
Databricks Engineering Solutions
Your data architecture needs a single Lakehouse platform that teams can govern and use. Our Databricks consulting services modernize the platform, automate processes, and unlock real-time predictive analytics and ML capabilities. The work can start with one failing pipeline or extend across the full platform. Our Databricks engineers focus each engagement on a measurable operational improvement, so architecture decisions support delivery instead of becoming an end in themselves.


What Our Databricks Engineers Fix in Real Projects
Our in-house team draws on 18 years of data engineering experience to stabilize broken data operations. The work spans legacy modernization, platform reliability, governance, and controls; they keep data usable as the business grows. The point is practical: remove the failure points that block delivery, make the environment easier to operate — leave the business with a system that the internal team can understand and maintain.

Legacy data systems that don’t scale
- Move workloads to Lakehouse with a clear separation of batches and threads.
- Apply autoscaling clusters that match real-world workloads.
- Break long tasks into smaller chunks that complete on time.

Manual SQL scripts & lack of automation
- Move logic into notebooks or workflows with version control.
- Add tests for each step.
- Set up scheduled Apache Spark jobs with alerts on failed runs.

Lack of data governance, provenance, and tracking
- Enable Unity Catalog for cataloging and access rules.
- Track every table and task with built-in provenance.
- Add quality checks on reads and writes.

Compliance, security, and access risks
- Lock down sensitive tables with table-level rules.
- Mask fields containing personal or business data.
- Log every read and write for audits.

Multiple unrelated data sources without a single platform
- Establish connectors for SaaS tools, applications, and repositories.
- Place all sources in a single Lakehouse zone.
- Standardize schemas so teams read data in the same way.

Unreliable pipelines and undocumented logic
- Refactor tasks with clear steps and up-to-date libraries.
- Add edge-case tests.
- Track task execution with alerts related to real errors.

Inefficient architecture increases compute costs
- Choose small cluster types for light workloads and autoscale for heavier workloads.
- Cache only what teams need.
- Remove obsolete tables and unused storage.
Business intelligence, AI, and advanced analytics don’t scale
- Create clean tables for dashboards.
- Create curated sets for machine learning.
- Add checks that block bad records before they spread.
Medical Lab Achieves 50% Compute Savings via Databricks Migration
Sagis Diagnostics, a leading U.S. pathology lab, replaced its fragmented Azure SQL setup with a unified Databricks Lakehouse built by Dataforest. The migration consolidated 21 data sources, automated analytics, and ensured HIPAA compliance — delivering full data transparency, pay-per-use efficiency, and a ~50% reduction in compute costs.


Medical Lab Achieves 50% Compute Savings via Databricks Migration
Streamlined Data Analytics
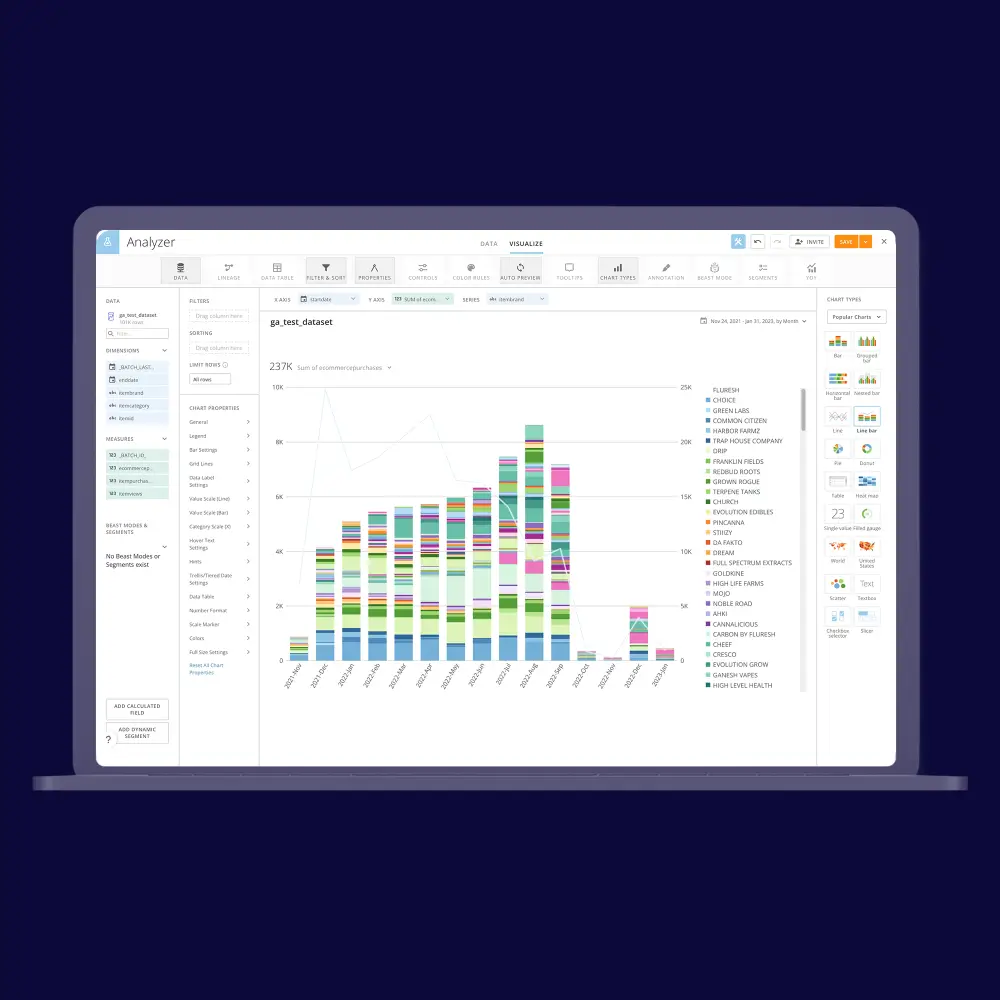
We helped a digital marketing agency consolidate and analyze data from multiple sources to generate actionable insights for their clients. Our delivery used a combination of data warehousing, ETL tools, and APIs to streamline the data integration process. The result was an automated system that collects and stores data in a data lake and utilizes BI for easy visualization and daily updates, providing valuable data insights which support the client's business decisions.

Their communication was great, and their ability to work within our time zone was very much appreciated.


All Success Stories

Reduce pipeline failures & data downtime by 50-70%
Engineers rebuild legacy SQL jobs into reliable Databricks ETL pipelines. These pipelines retry on errors, send alerts, and never fail silently.
Faster analytics and dashboard refreshes, up to 10-20x
Teams tune Delta tables and add intelligent caching. Dashboards that once took hours now refresh in minutes or seconds.

A unified Lakehouse for 10+ disparate systems
Engineers collect data from SaaS tools, databases, and APIs in one place. They organize it into bronze, silver, and gold tiers for clean operations.

Trusted provenance, governance & full visibility into data quality
Automated auditing records every change and validates data quality. Teams know exactly where data is coming from and trust what they use.
Faster insights with self-contained SQL and BI connectivity
Business users get fast SQL stores and clear data models. They create their own reports and bypass engineering wait times.
Our Databricks Technology Stack

Arangodb

Neo4j

Google BigTable

Apache Hive

Scylla

Amazon EMR

Cassandra

AWS Athena

Snowflake

AWS Glue

Cloud Composer

Dynamodb

Amazon Kinesis

On premises

AuroraDB

Databricks

Amazon RDS

PostgreSQL

BigQuery

AirFlow

Redshift

Redis

Pyspark

MongoDB

Kafka

Hadoop

GCP

Elasticsearch

AWS

Steps To Hire Expert Databricks Developers
We follow a clear delivery path to assign the right data expert from our own staff and get the first task moving quickly.

Define Project Needs
We review your data setup and requirements, then define the skills and delivery scope the assigned engineer will need.
01

Verify Credentials
We assign a certified engineer from our internal team whose previous internal deployments match the project requirements and technical context.
02

Test Technical Skills
The assigned engineer demonstrates technical capability in a live session and explains the architectural choices behind the proposed approach.
03

Begin Work
We set up accounts and permissions for the engineer. The engineer joins your team and starts the first task.
04

Track Progress
You receive a weekly report on the work completed. We check cloud usage to keep your budget low.
05
Articles That Encourage Hiring Databricks Developers
All publications
July 20, 2026
9 min
Top 5 Databricks Partners for Business Success in 2026

May 26, 2026
14 min
Data Lake Architecture for Unified Data Analytics Platform

May 1, 2026
15 min
Databricks Migration Guide: Retiring the Old Stack
Questions to Ask Before Engaging DATAFOREST's Databricks Team
Can you help us assess whether Databricks is the right platform for our needs?
We evaluate your daily data volume and target latency needs. Our team benchmarks your workloads against engines like Snowflake or BigQuery. We recommend a Databricks expert only to solve a verified operational constraint. A valid constraint reduces ETL execution time by half.
Can your engineers work with our existing Databricks configuration, or only with new projects?
Our engineers join active environments. They resolve technical debt. They fix broken pipelines. We review your cluster configurations and storage formats. We transition your tables to Delta format with liquid clustering. This format improves query speeds on your current setup.
Do you handle migrations from legacy systems (Hadoop, Azure SQL, Redshift, Snowflake, on-premises systems)?
We execute data migrations from legacy relational databases and on-premises clusters. Our process uses parallel extraction pipelines and staging zones. These zones prevent downtime during the transition. We validate the migrated data through automated row-count checks. Then we decommission your old infrastructure.
Can you integrate Databricks with our existing tools, SaaS systems, and cloud services?
We connect Databricks to your enterprise ecosystem. We use REST APIs and event streaming platforms like Apache Kafka. Your CRM platforms and marketing tools synchronize with your data lakehouse. We establish secure API gateways. They maintain continuous data flow between all active cloud services.
Do you provide end-to-end data and machine learning/LLM support on Databricks?
We manage the complete machine learning lifecycle. This covers raw data ingestion to final model endpoint deployment. Our team uses Databricks Feature Store to manage training data. We use MosaicML to fine-tune custom Large Language Models. Your predictive models move directly into active production environments.
Can your team build and automate pipelines, dashboards, and business logic workflows in Databricks?
We construct automated ETL pipelines. We use Databricks Workflows and dbt to process business logic on schedule. These pipelines feed directly into connected visualization tools like Power BI or Tableau. We connect them via SQL endpoints. Business users read refreshed dashboard metrics daily. They need no manual engineering intervention.
Do you offer ongoing support for monitoring, cost reduction & incremental improvements?
We configure automated Databricks SQL alerts. They monitor job failures and cluster health. Engineers perform monthly infrastructure audits. We downgrade oversized instances and update runtime versions. You hire certified Databricks developers from our team for proactive platform maintenance.
How do your engineers implement Databricks best practices?
We enforce strict version control and CI/CD automation. We also use Databricks Repos integrated with GitHub / GitLab. Every pull request undergoes automated unit testing. Then we deploy the code — the approach guarantees pipeline stability. Your data platform remains reliable, and your codebase grows without issues.
How do you manage documentation, adoption, and knowledge transfer to our team?
We maintain comprehensive architecture diagrams and code-level data dictionaries. We build these within Confluence or your preferred internal wiki. We lead pair-programming sessions and practical workshops. Sessions target your data analysts and data engineers. Your internal staff then operate and expand the platform independently.
How much does it cost to hire a Databricks developer from DATAFOREST?
Pricing depends on the engagement model. Targeted consulting is billed hourly, while a dedicated Databricks team uses a flat monthly fee; fixed-scope work is priced against the defined delivery scope. Companies that hire Databricks developers receive a quote based on the required seniority, scope, and delivery model rather than a generic rate.
Can you estimate the timeline and cost of our migration or modernization project?
We calculate precise timelines during a specialized scoping workshop. We evaluate your source data formats and dependency map. The technical assessment identifies potential migration blockers. We find these blockers early. We write no infrastructure code during this phase. Then you receive a detailed statement of work. This document contains sprint milestones and a fixed budget.
How quickly can the team start, and what does ramp-up look like?
We assign a dedicated technical team within two weeks of finalizing the contract. The team completes the initial environment configuration in 24 hours. They gain repository access on day one. The engineers begin analyzing your source systems on the second day. They start writing infrastructure code immediately.
How do you control costs and prevent overspending on Databricks compute resources?
We manage cluster settings to cut unnecessary resource usage and implement autoscaling policies. These policies knock cluster idle time down to under 10 percent. Our engineers select spot instances for non-critical batch processing. They adjust shuffle partitions to reduce heavy compute loads. Platform configurations lower monthly cloud consumption bills. They maintain your expected pipeline execution times.
How do you maintain data quality, reliability, and pipeline observability?
We integrate automated validation frameworks like Great Expectations into your ingestion pipelines. The frameworks drop malformed records instantly. We route execution logs and error metrics into centralized Databricks SQL dashboards. Job failures and data skews trigger alerts. They pinpoint the exact node and query. This stops small processing errors from corrupting downstream business reports and gives companies a clearer basis to hire Databricks developers for a defined operational outcome.
Let’s discuss your project
Share project details, like scope or challenges. We'll review and follow up with next steps.


